Context window
AI doesn't remember your chat
A model can only read so much text at once, and it re-reads the whole chat every time you hit send. That's why long chats start losing track of things.
By Laksh2 min readUnderstanding AI and LLMs
 Watch the reel32 s · InstagramWatch ↗
In short
A context window is the amount of text, measured in tokens, that a language model can read at once, including its own reply. The model keeps no memory between messages, so the app sends the whole chat again every time. When a chat outgrows the window, older parts get dropped or summarised, which is why it seems to forget.
Ever had a long AI chat where it suddenly forgets something you told it an hour ago? That's not a glitch. It comes from how these models read.
The model reads, it doesn't remember
A language model can only take in so much text at once. That limit is its context window, and it's measured in tokens. Anthropic describes it as the model's working memory: everything it can look at while it writes a reply, including the reply itself.
Both sides of the chat use it up. Your messages count, and so do the model's answers.
Every message sends the whole chat again
The model itself keeps nothing between messages. OpenAI's docs put it plainly: each request is independent and stateless. So every time you hit send, the app sends the entire conversation so far back to the model, with your new message on the end.
In a short chat that's fine. In a long one, the conversation eventually stops fitting.
When it runs out of room
Apps deal with that in a few ways. A common one is to drop the oldest messages first. Another is to summarise earlier parts of the chat into something shorter. Either way, details from early on can get lost. (The API is stricter: if the input alone is too long, it refuses the request.)
Memory features in chat apps don't change this. They work by putting saved notes back into the context window.
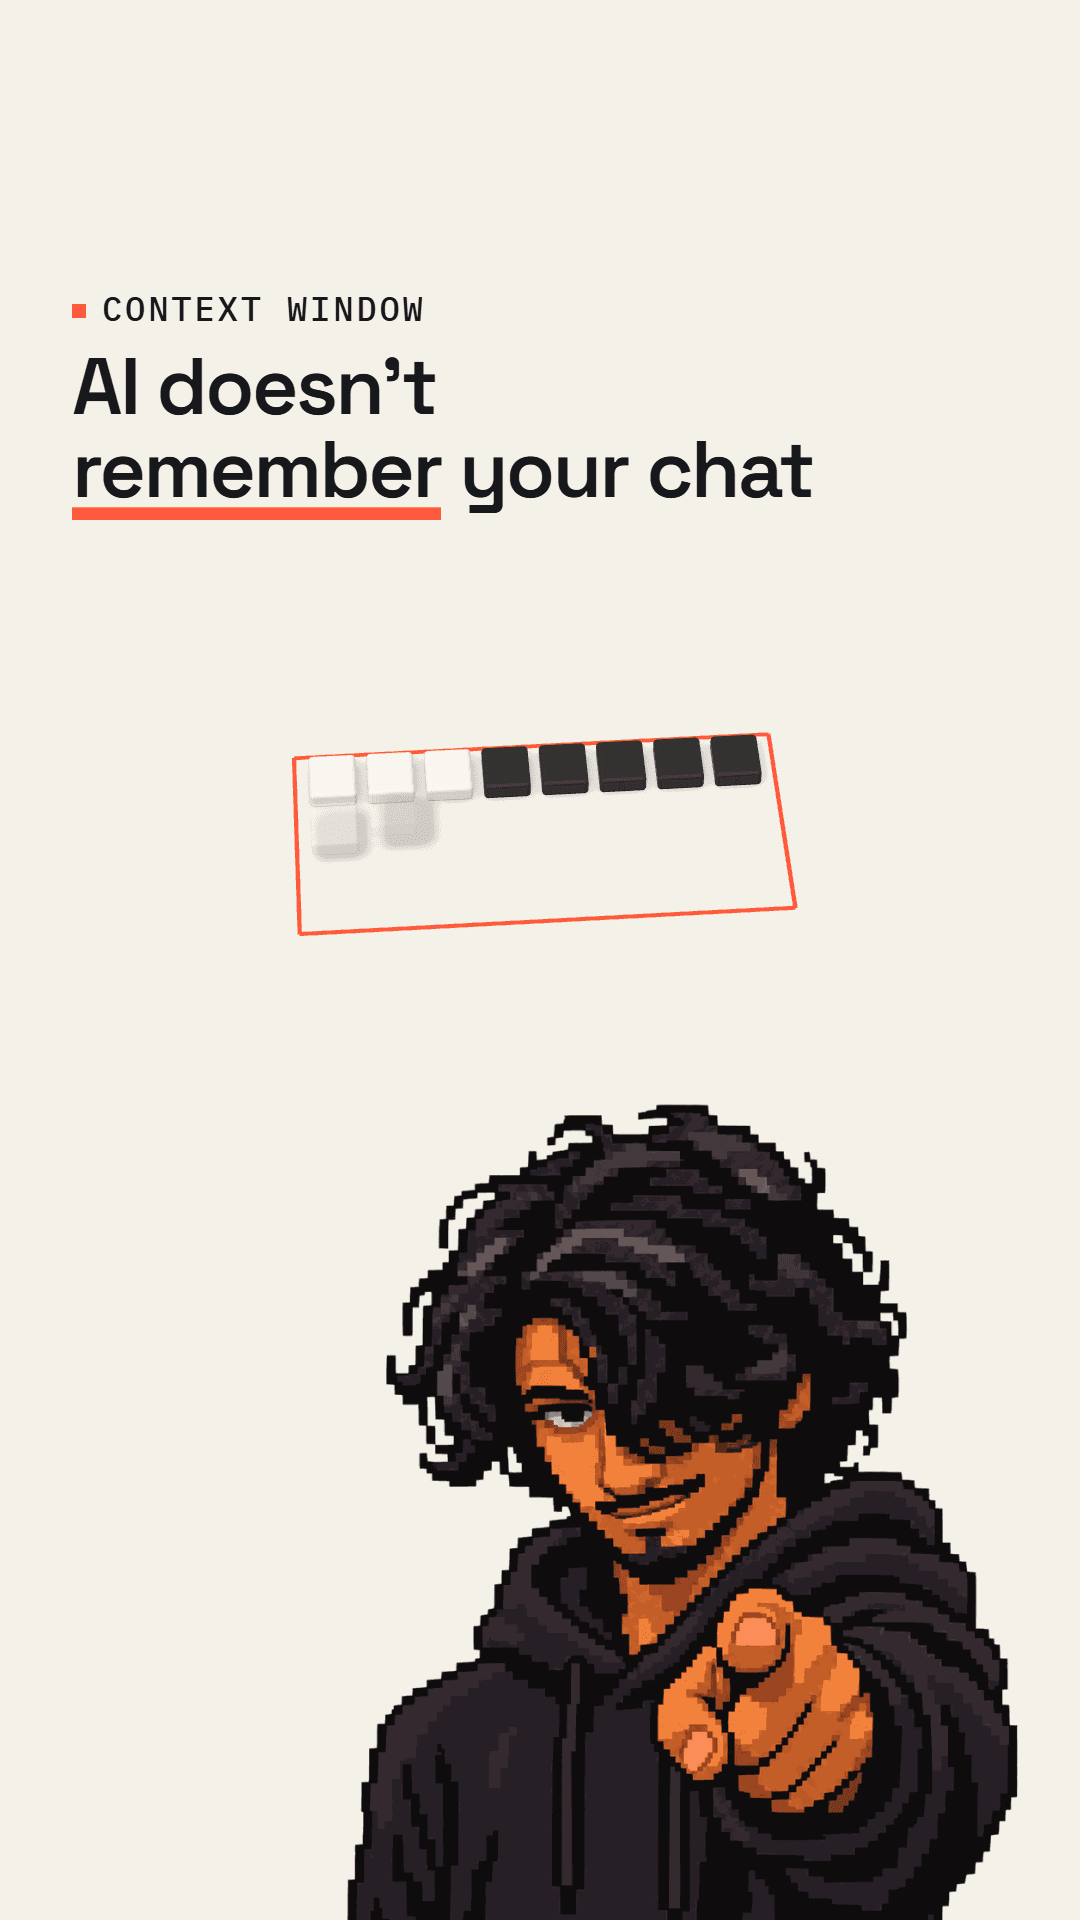
The 24-tile window in the video is a toy scale, not a real model's size.
Bigger windows help, up to a point
Some Claude models now fit around a million tokens, which is roughly 750,000 words of English. That's a lot. But a bigger window isn't automatically better: Anthropic's own docs say accuracy and recall can drop as the context grows.
There's also a well-known finding from 2023: models tend to use information at the start and end of a long context best, and miss things buried in the middle. That study tested 2023 models, so treat it as a pattern, not a number for today's models.
What to do about it
If the model forgets something that matters, just remind it. A short restatement lands at the end of the window, where it's easiest to use.
Sources
- 01Context windows
Anthropic, Claude docs
- 02Conversation state
OpenAI API docs
- 03Lost in the Middle: How Language Models Use Long Contexts
Liu et al., TACL 2023
- 04Understanding and counting tokens
OpenAI Help Center
Spotted a mistake? Tell me and I'll fix it.
Newsletter
New explainer? You hear first.
Each one is a single AI concept, explained in plain words, with the sources linked.